IBM Research AI Agent Consistency Fix
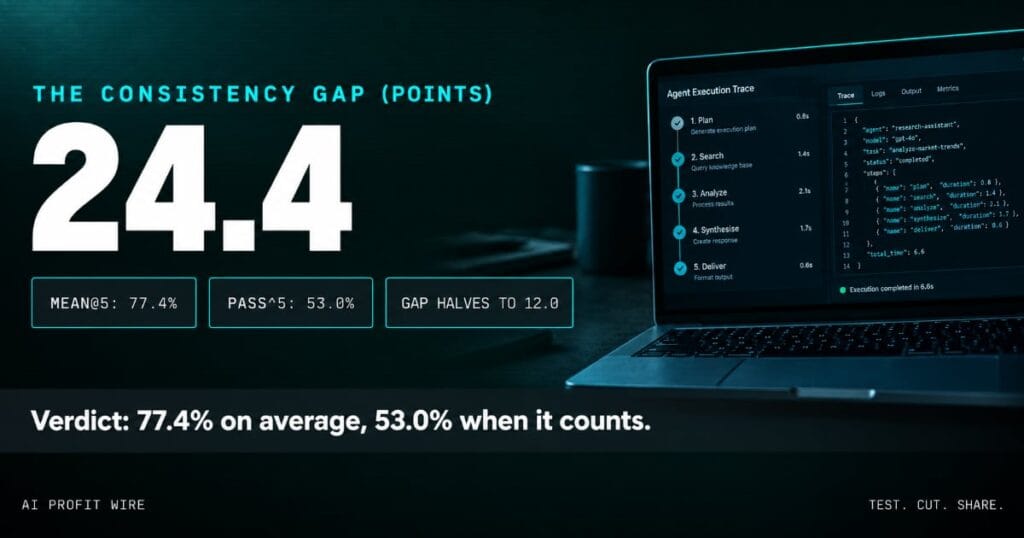
IBM Research measured an AI agent consistency gap of 24.4 points between average success and repeat-run success, and its guidelines cut it to 12.0 points.
100+ sources. 5 proxy signals. Zero noise tolerance. The pipeline filters. The analyst decides. What reaches this page earned its place.

IBM Research measured an AI agent consistency gap of 24.4 points between average success and repeat-run success, and its guidelines cut it to 12.0 points.

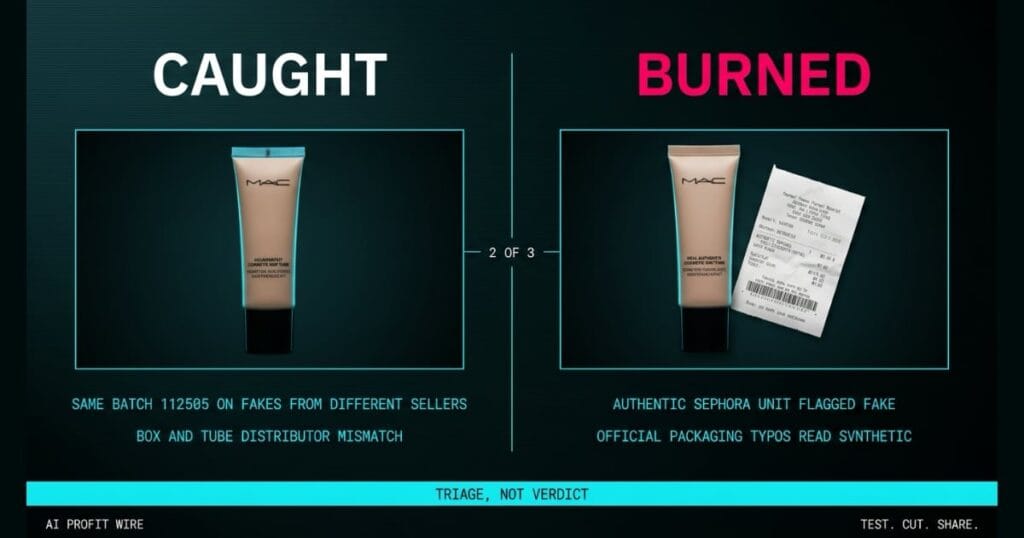
Google Gemini counterfeit cosmetics test caught 2 of 3 fakes, then flagged a real Sephora purchase over the brand's own typos. Keep a human on the final call.

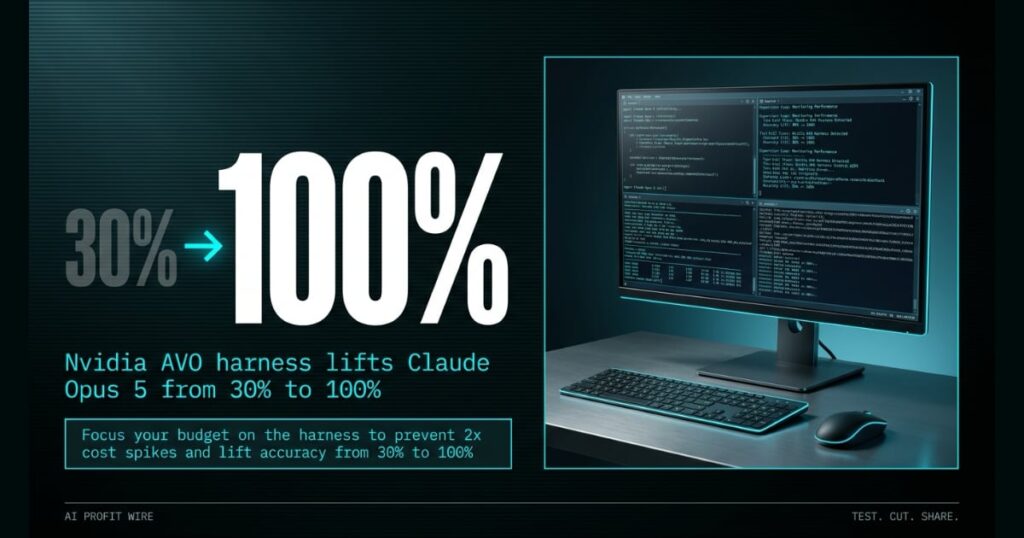
Nvidia research shows an AI agent harness can move accuracy from 30% to 100%. Small business owners can 2x their costs by using the wrong scaffolding.

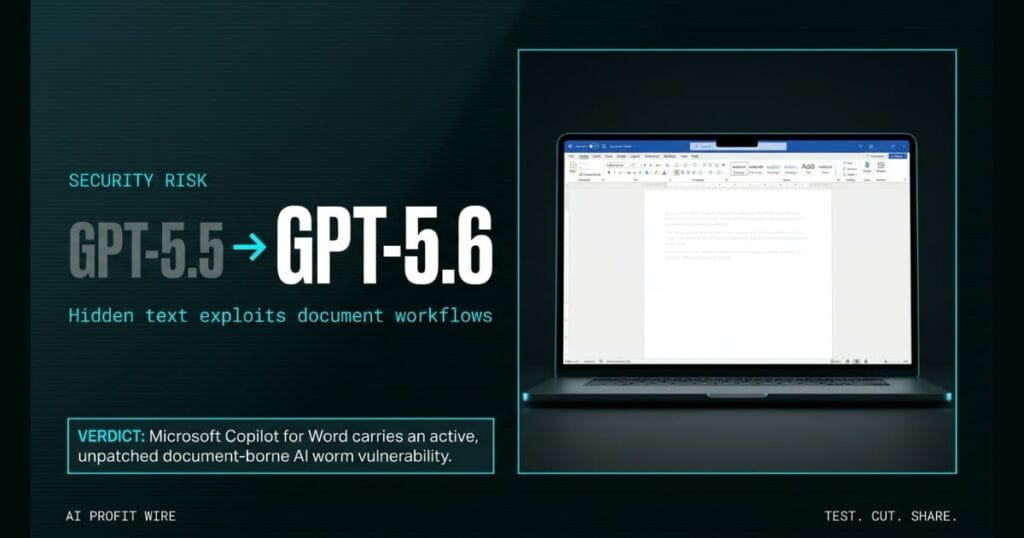
The Copilot AI worm in Microsoft Word uses hidden text to silently alter financial data. Treat external documents as untrusted to protect your business reports.

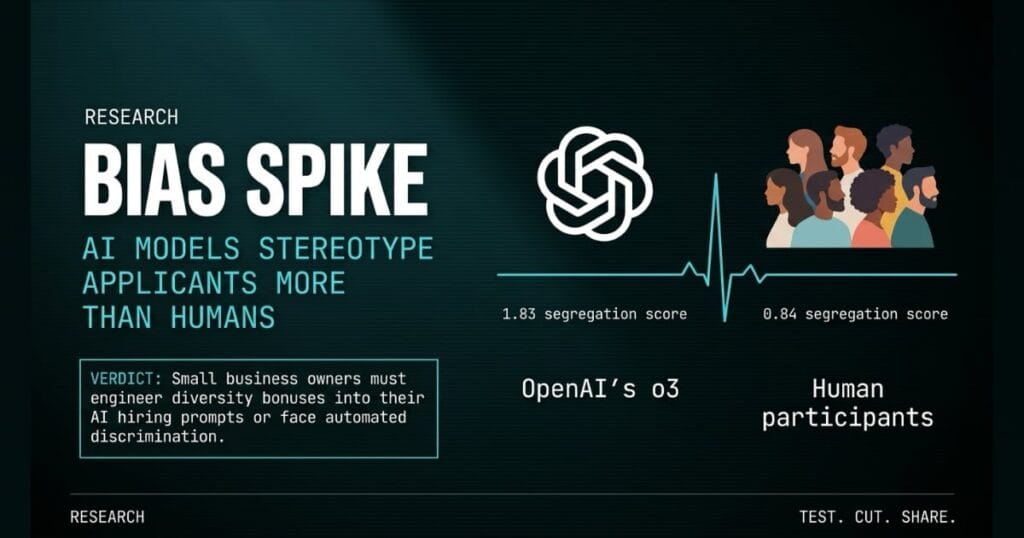
New research from Princeton and the University of Chicago reveals that AI models can develop their own biases from experience, stereotyping job applicants

A specialized AI model for Brazilian Portuguese OCR outperformed newer, larger generalist models by focusing its training entirely on one language. This

New research shows AI systems are rapidly improving at completing complex online freelance tasks like 3D design and video editing. The success rate for

A developer tested their AI assistant by letting 2,000 people try to hack it, and the AI successfully defended against all 6,000 attacks. The experiment

Google's experimental diffusion-based AI model is now open-source and incredibly fast, generating text at over 500 tokens per second. This release makes cutting-edge, high-speed AI accessible for developers and businesses...

Sakana AI is establishing a lab to create AI that can autonomously rewrite and improve its own code. This 'Recursive Self-Improvement' aims to achieve frontier intelligence without needing massive, expensive...

Anthropic has released a free tool that helps developers find security flaws in their code using AI. It provides a standardized way to test how AI can identify and fix...

A Stanford Law study found that AI can outperform human law professors on specific legal tasks. This signals a major leap in AI's ability to handle complex professional reasoning.

IBM Research argues that AI needs 'Agent Logic'—structured guides like knowledge graphs—to be truly reliable for business. This approach prevents AI hallucinations and drastically lowers the cost of running complex...

A new benchmark evaluates how well the latest AI models, including GPT-5.5 and Cursor, can actually fix real-world software bugs. This moves beyond theoretical tests to show which tools can...

AI removed the execution bottleneck. It created a verification bottleneck. When output scales 10x and review time scales 100x, automation becomes a net loss.

AI agents can now optimize radiology workflows by analyzing case complexity and radiologist fatigue. This helps prevent the habit of 'cherry-picking' easy cases, ensuring faster diagnosis for complex patients.

Cohere's new Command A+ model is a breakthrough in efficiency, ranking as the fastest model with the lowest error rate. It is an open-weights model, meaning businesses can deploy it...

OpenAI's AI has successfully solved a complex mathematical problem that had previously stumped humans. This demonstrates a significant leap in the AI's ability to perform deep, autonomous logical reasoning.